A scene with real depth doesn’t happen by accident. Every strong composition, whether it’s a painting, a photograph, or a generated image, relies on decisions about what sits in front, what recedes into the background, and how the eye is meant to travel across all of it. Skip those decisions and even a technically sharp image can feel flat. An AI image generator can absolutely build that kind of layered depth, but only when the prompt actually accounts for composition rather than just naming a subject. Dreamina, running on its newest model Seedream 5.0 Pro, rewards this kind of compositional thinking more than most tools.
Why composition matters more than subject matter alone
It’s easy to assume a strong scene just needs an interesting subject. In practice, the same subject can look completely different depending on how it’s arranged in space. A figure standing dead center against a flat backdrop reads very differently than that same figure placed slightly off-center with a layered environment behind it. Composition is what turns a subject into a scene.
The layers that build genuine depth
A composition with real depth usually separates into a few distinct planes. Worth deciding before writing a prompt:
- Foreground detail, close and slightly softer or sharper depending on focus
- A mid-ground where the main subject or action typically sits
- Background elements that add context without competing for attention
Naming these separately, rather than describing a scene as one flat idea, tends to produce far more convincing depth.
Meet Dreamina’s Seedream 5.0 Pro
Seedream 5.0 Pro handles layered composition well because it reasons through spatial relationships before generating, working out how foreground, mid-ground, and background elements should sit relative to each other rather than flattening everything into one plane. Point selection, lasso tools, and sketch guidance let you adjust one layer of a scene, a foreground element, a background detail, without disrupting the rest of the composition. Layer separation takes this further still, letting subject, background, and effects shift independently even after the initial generation. With 2K output holding fine detail across every plane of the scene, built-in research keeping environmental choices grounded, and native text support across 14 languages for scenes needing signage or environmental text, it’s a model genuinely built for compositional depth.
Building a scene with real depth, step by step
This is where the composition actually starts coming together. Here’s how it plays out inside Dreamina.
Step 1: Write a text prompt and/or add reference image
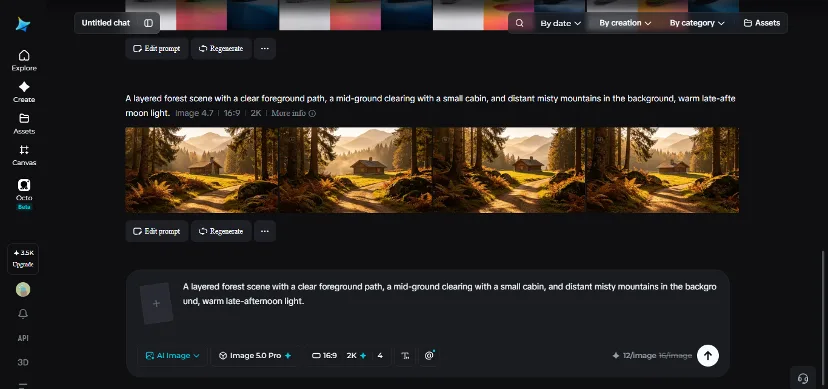
Head to Dreamina and describe your scene in layers, foreground first, then mid-ground, then background, along with lighting and mood. Upload a reference image if you already have one that captures part of the composition you’re picturing.
A sample prompt might read: “A cobblestone path leading through a quiet forest clearing, a wooden cabin nestled among the trees at mid-distance, distant misty hills fading into the background, warm golden hour light, layered natural depth.”
Step 2: Adjust parameters and generate
Choose Image 5.0 Pro by Seedream 5.0 Pro as your model. Set aspect ratio and size based on where the composition will be used, then pick resolution, 1K to check whether the depth is reading correctly, 2K once the composition holds together. Click Dreamina’s icon once it’s set, and let it generate.
Step 3: Customize and download
A layered scene rarely lands perfectly on the first attempt, especially across multiple planes at once. Use inpaint, expand, remove, and retouch to adjust a background element that’s pulling too much focus or sharpen a foreground detail that got lost. Once the depth feels right, hit “Download.”
Guiding the eye through a composition on purpose
A scene can have all the right layers and still feel disorganized if nothing guides the viewer’s attention. A few habits help direct that flow:
- Use a clear leading line, a path, a fence, a shoreline, to pull the eye inward
- Keep the busiest detail in the mid-ground, where attention naturally lands first
- Let the background stay simpler, so it supports depth without stealing focus
Without this kind of intentional guidance, even well-separated layers can end up competing rather than cooperating.
Mistakes that flatten an otherwise strong composition
A handful of habits tend to undercut layered scene work specifically. Treating every plane with equal visual weight leaves nothing for the eye to settle on, since a composition needs a clear priority rather than three competing focal points. Overcrowding the background causes a similar problem, pulling attention away from the mid-ground where the subject usually belongs. Describing a scene as one flat list of elements, rather than as layers with real spatial relationships, tends to produce exactly that: a flat result, no matter how detailed the description was.

Where detailed compositional work is worth the effort
This kind of layered scene-building tends to matter most in a specific set of situations. Concept art and environmental design benefit heavily, since believable depth often separates a convincing world from a flat backdrop. Editorial and cinematic photography follow a similar pattern, relying on composition just as much as subject to carry mood. Game and animation pre-production gets real value here too, since environments built with genuine depth translate more naturally into three-dimensional spaces later.
Wrapping up
A detailed composition was never just about cramming more into the frame, it’s about arranging what’s there with real intention behind every layer. With Dreamina and Seedream 5.0 Pro, that kind of depth becomes a lot more achievable from a single prompt, giving a scene the same sense of space and priority a skilled photographer or painter would build in by hand.